Field Notes
Thirty Characters a Second
The story traces how real-time text moved from phone calls into meetings, where a new filing asks whether typing can count as speaking.
What changes in this design
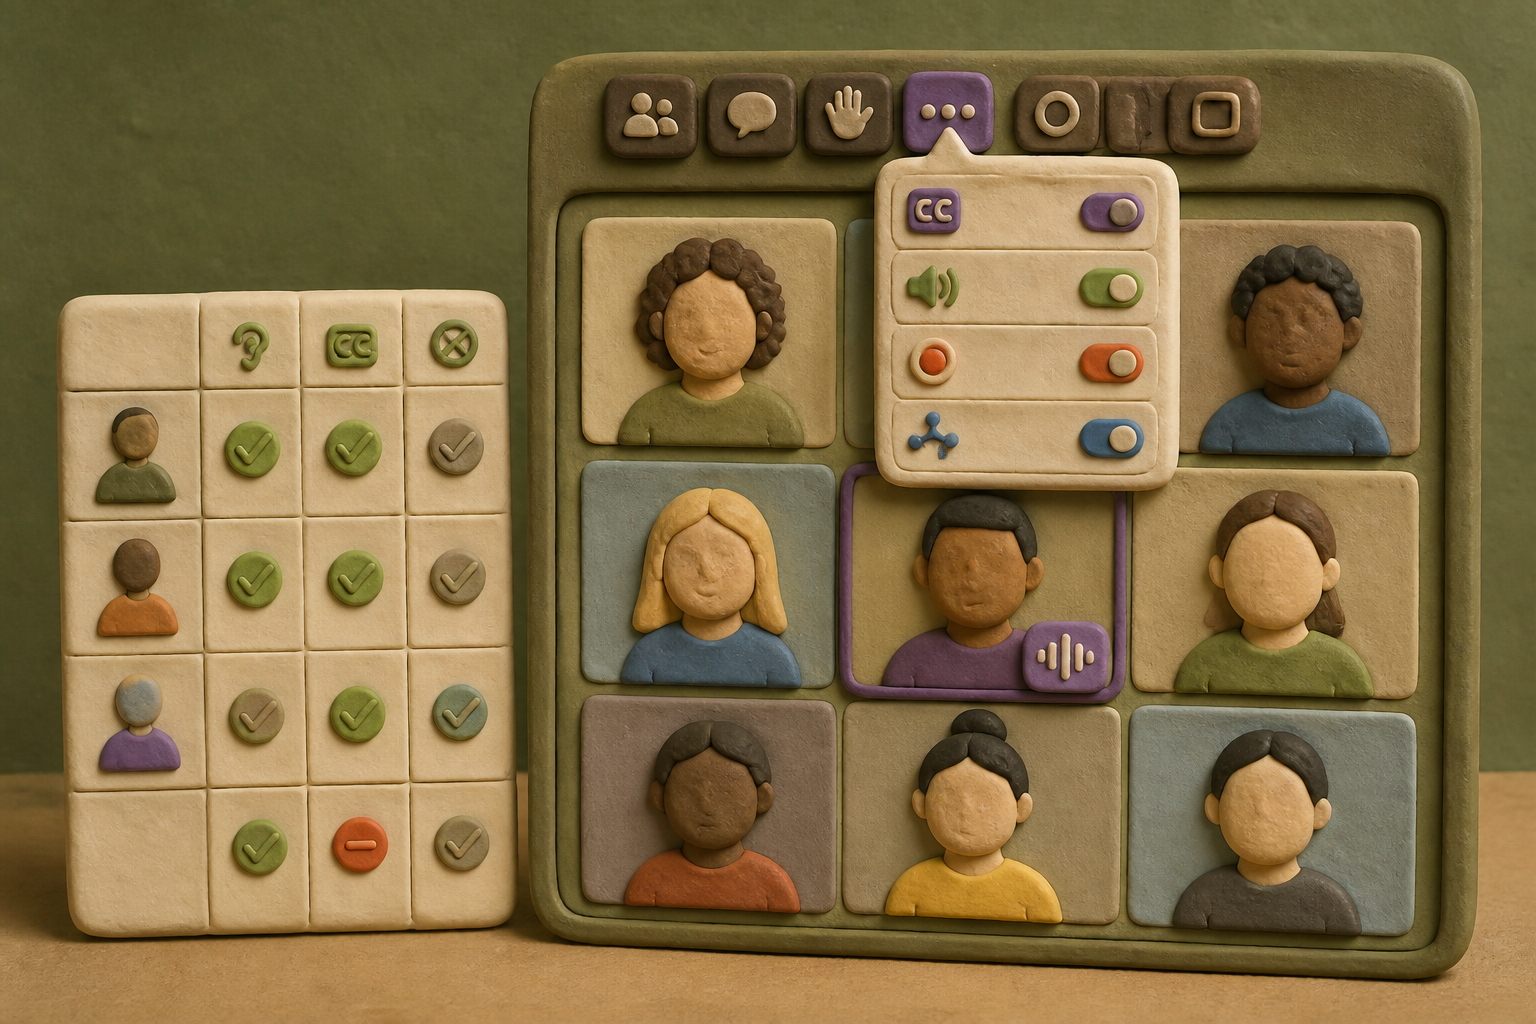
Without this feature, a reader might simply expect live typed messages to appear in a meeting without a highlighted name or image for a designated participant or an active-speaker label.
Here, a participant using real-time text has a highlighted name or image if they are designated as having a prerequisite. The system marks that participant as an active speaker, manages conversion of typed text into speech, and records the live text in meeting records.
This may matter because the link between a person and their live typed words becomes visible. It also ties that status to spoken rendering of the text and to inclusion in the meeting record. What the prerequisite is and how the controls operate are not stated.
Thirty characters a second
The number that makes conversation mechanical for me is 30 characters a second. RFC 4103, a 2005 standard for carrying T.140 text conversation over real-time transport, sets that default rate cap. It recommends about 300 milliseconds of buffering, with 500 milliseconds maximum for T.140. It is not a chat box waiting for a polished sentence. Text reaches the other person while a thought is still forming.
About 37.5 million U.S. adults, or 15 percent, report trouble hearing. For many, RTT keeps them in a call's pace without every word being spoken or heard. In 2016, the FCC ordered a transition from TTY toward RTT on phone networks. That history was a reminder to me that this began as basic access, not a meeting feature.
May 2025
The recent arrival of that phone-era idea in a mainstream video meeting surprised me. Teams added RTT in May 2025, sending text character by character without an Enter key so conversation can keep moving. Microsoft's administrator guidance says RTT is on by default and uses dedicated data channels. It works in meetings, group calls, one-to-one internet calls, room systems and compliance recordings, but not the public telephone network, emergency calling, events or end-to-end encrypted meetings. The same guidance says RTT enters a recording only when captions are on, with storage following transcription.
A January 2026 companion application that I found treats the same territory as one surface: RTT alongside video, captions, transcripts and Copilot. A meeting record cannot use a typed contribution if the system sees it as a side channel. The question is no longer whether text can arrive live. It is whether the meeting will recognize who said it, how it should be heard, and what happens after the call.
January 12, 2027
While I was reading about RTT, I found a nearby deadline that sharpens the stakes. The FCC's December 2024 video-conferencing order requires captions to be verbatim and synchronous, and it requires caption controls that an individual can use without a host's permission. Compliance is due January 12, 2027. Those rules put the reader, not the meeting host, at the center.
But the FCC did not make RTT a safe-harbor technical route, despite a proposal to use the relevant standard. It also declined to require text-to-speech, leaving that issue for a later proceeding. That restraint was sensible, I think. Captions and RTT can overlap, but they answer different needs: one renders spoken audio as readable text; the other lets a participant contribute live through text. Treating them as interchangeable would hide the design choices this filing exposes.
A typed active speaker
A warning in the W3C accessibility requirements kept drawing me back: send the fragments of RTT straight to text-to-speech and the output can stutter until it becomes hard to understand. That is a small technical failure with a social cost. A participant may have written clearly, yet the room hears a broken approximation.
The filing I found at that fault line was US20260254782A1. It proposes dynamic control of turning RTT into speech and stronger visual attribution for a participant using RTT. It would highlight a participant's name or image when that person is designated and using RTT. The system can also mark that person as an active speaker, so the text becomes part of the meeting record and can feed associated automated systems. The system struck me as an attempt to give typed participation the same institutional weight as spoken participation.
What the filing is really betting on
That is a consequential bet. The benefit I can see is that attribution can stop RTT from disappearing into an uncredited transcript, and careful speech conversion can make a text contributor legible to people who are listening. Yet I also found a privacy limit that should keep us cautious. A 2025 rollout tracker reports that, when transcription is off in Teams, live captions and RTT show only the most recent five minutes of dialogue. That boundary sits uneasily beside a system designed to place RTT in lasting records and automated systems.
The filing identifies the right problem but, in my view, makes recognition too easy to confuse with consent. An RTT participant should be visible when they want to be visible, and their words should enter records or automated analysis only under controls they can understand and change. The technology is ready to type alongside speech. The harder work is deciding when a participant has also agreed to be heard, remembered, and processed as a speaker.
Sources
Reporting for this piece drew on the published filing and the references below.
- Enhanced Visual Indicators For Designated Participants Communicating Real-Time Text
- RFC 4103: RTP Payload for Text Conversation
- Quick Statistics About Hearing
- ICYMI: FCC Approves RTT as an Update to TTY
- Here are all the new features Microsoft added to Teams in May 2025
- Manage real-time text (RTT) in Teams for users in your organization
- Enhanced controls for the display of real-time text in calls and meetings
- Access to Video Conferencing, Second Report and Order
- RTC Accessibility User Requirements
- Microsoft Teams: Enhanced privacy and improved stability for live captions and transcripts
The record, briefly. US20260254782A1, “Enhanced Visual Indicators For Designated Participants Communicating Real-Time Text” Techniques give enhanced control of visual indicators attributing participants who communicate via real-time text (RTT) in online meetings, plus dynamic control of text-to-speech conversion of RTT. A person's name or image is highlighted if designated as having a prerequisite while in RTT mode, and the system marks such users as an "active speaker" so RTT content is recorded in meeting records and used in AI models.
More angles on this
- One window, several models: a reading of Model Functionality MonitoringAnother reading from the same H04L classification family, transmission of digital information, e.g. telegraphic communication.
- When Context Changes Hands in Healthcare InformationAnother reading from the same G06F classification family, electric digital data processing.
- CPC H04L: Transmission of digital information, e.g. telegraphic communicationThe official classification family this record was filed into, published in the USPTO Cooperative Patent Classification scheme.
- CPC G06F: Electric digital data processingThe official classification family this record was filed into, published in the USPTO Cooperative Patent Classification scheme.
- The Substrate That Gave Its Two Recesses Unequal DepthAnother reading from the neighbouring H04N classification family, pictorial communication, e.g. television.
Read around this one:Public patent recordUSPTO published figure